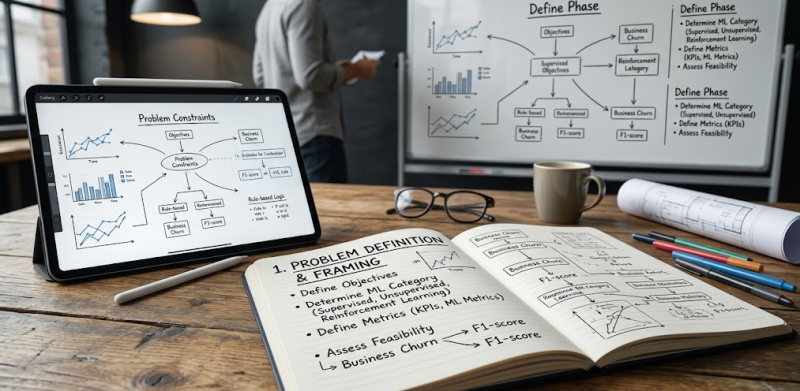
1. Problem Definition & FramingBefore writing code or gathering data, the problem must be clearly articulated in business and technical terms. - Define Objectives: Identify the core business problem and how a machine learning model will solve it.
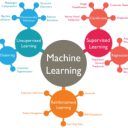
- Determine the ML Category:
- Supervised Learning: Classification (predicting discrete labels) or Regression (predicting continuous values).
- Unsupervised Learning: Clustering (grouping data) or Dimensionality Reduction.
- Reinforcement Learning: Decision-making based on reward signals.
- Define Metrics: Establish success criteria using both business KPIs (e.g., reduced customer churn) and machine learning metrics (e.g., F1-score, RMSE).
- Assess Feasibility: Ensure sufficient, relevant data is available and that machine learning is the appropriate solution compared to rule-based logic.
2. Data Collection & PreprocessingData quality directly dictates model performance. This stage focuses on turning raw data into a usable format. Data Acquisition & Integration- Gather data from SQL/NoSQL databases, web scraping, APIs, or flat files.
- Ensure data privacy and compliance (GDPR, HIPAA, etc.).
Data Cleaning- Missing Values: Handle missing data using imputation (mean, median, mode) or removal.
- Outliers: Identify and manage anomalies using statistical methods (Z-score, IQR).
- Duplicates: Detect and drop redundant observations.
Exploratory Data Analysis (EDA)- Visualize data distributions using histograms, box plots, and scatter plots.
- Analyze correlations between features to detect multicollinearity.
- Identify class imbalances in target variables.
Feature Engineering & Transformation- Categorical Encoding: Apply One-Hot Encoding, Label Encoding, or Target Encoding.
- Feature Scaling: Normalize (MinMax) or Standardize (StandardScaler) numerical features so algorithms process them equally.
- Feature Creation: Combine or transform raw features to extract stronger predictive signals (e.g., extracting "day of week" from a timestamp).
- Feature Selection: Filter out non-informative features using techniques like Variance Thresholding, Lasso Regularization, or Feature Importance scores.
Data Splitting- Training Set: Used to train the algorithm (typically 70-80%).
- Validation Set: Used to tune hyperparameters and prevent overfitting (typically 10-15%).
- Test Set: Held out to evaluate final model performance on unseen data (typically 10-15%).
3. Model Selection & TrainingSelecting and training the right algorithm is an iterative process starting from simple baselines. Baseline Modeling- Build a simple statistical rule or a basic model (e.g., Logistic Regression or Mean Predictor) to establish a benchmark for performance.
Algorithm Selection
Select appropriate models based on data type, dataset size, interpretability requirements, and computational resources:
- Linear Models: Linear Regression, Logistic Regression (fast, highly interpretable).
- Tree-Based Models: Decision Trees, Random Forests, XGBoost, LightGBM (handles non-linear data well).
- Neural Networks: Deep Learning for complex unstructured data (images, text, audio).
Hyperparameter Tuning
Optimize model configuration parameters that are not learned automatically during training:
- Grid Search: Exhaustively searches through a specified set of hyperparameter values.
- Random Search: Randomly samples hyperparameter configurations (more efficient than Grid Search).
- Bayesian Optimization: Uses probability models to efficiently find optimal hyperparameters (e.g., Optuna, Hyperopt).
4. Evaluation & ValidationThorough evaluation ensures that the model generalizes well to new, real-world data without overfitting or underfitting. Cross-Validation- Perform K-Fold Cross-Validation (or Stratified K-Fold for imbalanced datasets) to evaluate performance across different subsets of the data and prevent sampling bias.
Key Evaluation Metrics- Classification Metrics:
- Accuracy: Overall correctness (misleading for imbalanced data).
- Precision: Ratio of true positives to total predicted positives (minimizes false positives).
- Recall (Sensitivity): Ratio of true positives to actual positives (minimizes false negatives).
- F1-Score: Harmonic mean of Precision and Recall.
- ROC-AUC: Measures discrimination capability across trade-offs between True Positive and False Positive rates.
- Regression Metrics:
- Mean Absolute Error (MAE): Average magnitude of errors.
- Mean Squared Error (MSE) / Root Mean Squared Error (RMSE): Penalizes larger errors more heavily.
- R2 Score: Proportion of variance in the dependent variable explained by the model.
Diagnosing Performance Issues- Overfitting: High training accuracy, low validation accuracy. Remedies: Add regularization (L1/L2), drop features, reduce model complexity, or gather more data.
- Underfitting: Low training accuracy, low validation accuracy. Remedies: Increase model complexity, engineer better features, or relax regularization.
5. Deployment & Integration (MLOps)Once validated, the model is packaged and made available for end-users or internal systems. - Model Serialization: Save the trained model artifact using formats such as Pickle, Joblib, ONNX, or TensorFlow SavedModel.
- API Development: Wrap the model in a REST or gRPC API framework (e.g., FastAPI, Flask, BentoML).
- Containerization: Package the application, dependencies, and model binaries using Docker to ensure consistent behavior across environments.
- Serving Strategies:
- Batch Inference: Predicts in bulk at scheduled intervals.
- Real-time Inference: Returns instant predictions via low-latency API calls.
- Edge Deployment: Runs models directly on local hardware/devices (e.g., mobile apps, IoT).
6. Monitoring & MaintenanceMachine learning models require ongoing operation and updates after deployment due to real-world changes. - Performance Monitoring: Track latency, system uptime, prediction distribution, and hardware resource utilization.
- Drift Detection:
- Data Drift: Changes in the statistical distribution of input data over time.
- Concept Drift: Changes in the underlying relationship between inputs and target variables.
- Continuous Retraining Pipelines: Automate periodic retraining on fresh data to maintain model accuracy and relevance.
|